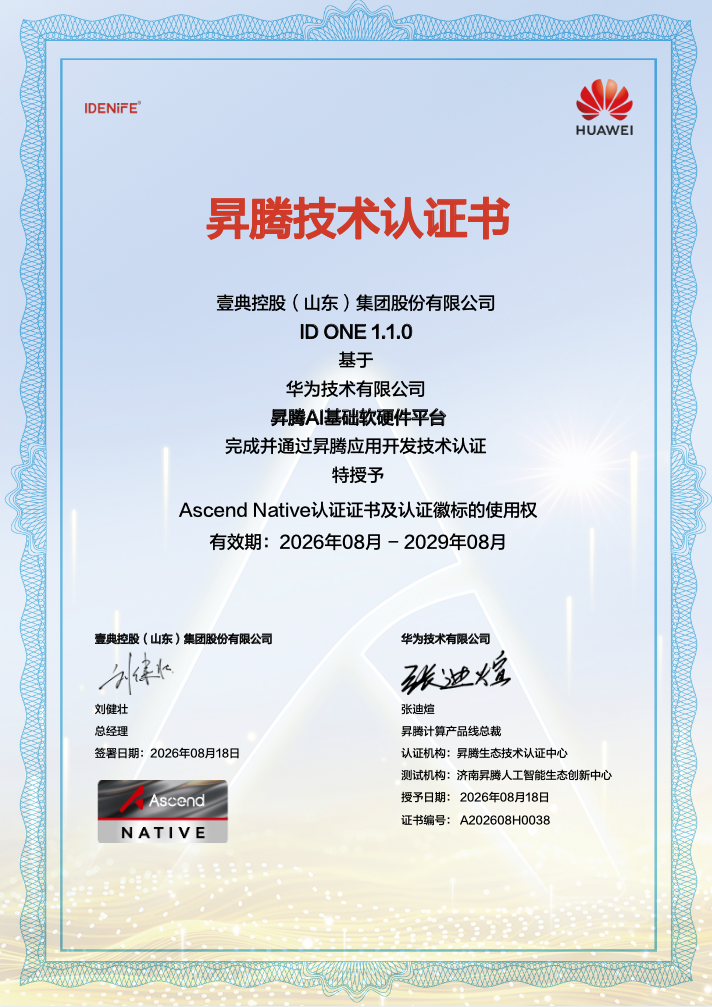
ID ONE 1.1.0 Ascend certified
Ascend Native application development certification connects enterprise applications with the technology ecosystem.
Certification dateRead article
Explore enterprise products and AI capabilities built for industry.
Let’s talk about your businessProducts, integrations and partnershipsBring AI into the enterprise.
Connect AI to products and operations.
Explore the interfaces and integration paths for our AI capabilities.
Models, foundational frameworks and the engineering behind AI systems.
Explore collaboration across products, technology and delivery.
Frameworks, tools and examples for developers to understand and reuse.
Updates, technical thinking and industry observations from IDENIFE.
Our focus on education, talent and sharing knowledge.
InsightsIDENIFE
Updates, technical thinking and industry perspectives from IDENIFE. Following technology as it becomes part of everyday work.
Ascend Native application development certification connects enterprise applications with the technology ecosystem.
Warehouse proximity filters, asset matching and service-radius reports can be wrong even when their SQL executes successfully. Using PostGIS, this article separates coordinate provenance, axis order, reference-system assignment and transformation. A constructed two-kilometer example, ingestion procedure and boundary tests explain reliable distance queries and their limits.
Lower GPU power does not necessarily mean a more energy-efficient AI service. This article separates power, energy and emissions, then examines measurement boundaries, quality, deadlines and idle time. A constructed example and a reproducible evaluation procedure help enterprise teams distinguish credible savings from incomplete comparisons.
Late events can be discarded, counted twice or cause newer results to be overwritten. A worked timeline and acceptance procedure distinguish event-time progress, retained windows, updated totals and corrections after window closure.
Different labels can reveal mistakes, missing evidence, conflicting policies or legitimate interpretations. A worked example and a practical review framework show when to correct labels, redesign the task or pause expansion.
A successful archive upload does not make every member safe for a data pipeline. This article separates archive names from storage addresses and compressed size from resource use, then defines isolated processing, complete manifests, streaming limits and whole-batch publication, with constructed failure and recovery cases.
Compressing several reports into one conclusion can make repeated retellings look like independent confirmation and mix incompatible versions. A constructed supplier review illustrates source dependencies, unresolved differences and required-question checks, helping teams choose between a short summary, an evidence table and direct review.
A successful HTTP request and a matching file size do not prove a correct download. This article distinguishes versions, byte ranges and checksum scopes, explains resume responses and encoded representations, and develops a recoverable staging-to-delivery process with a fault acceptance matrix.
A more accurate forecast does not establish an executable schedule. This article separates hard constraints, preferences and objectives, then develops a constructed example and an acceptance process covering independent checks, disruption replay and controlled release.
Summing fault durations can count the same minute repeatedly, while comparing only the previous end time fails on nested intervals. This article develops a downtime contract, two implementation paths and counterexample tests for clipping, open events, overlapping causes and missing evidence.
Lower average forecast error does not necessarily reduce shortages or excess stock. This article connects quantile forecasts with asymmetric costs and replenishment constraints, using a constructed example and a practical evaluation process that separates probability quality from the value of inventory decisions.
A normal-looking spreadsheet date can shift by years, turn a duration into a time of day or move a business date to the previous day. This guide separates Excel date systems, stored representations and business types, with pre-conversion checks, counterexamples and recoverable corrections.
A coherent rationale does not establish why a model reached its answer. Separate explanations, source evidence, reproducible checks and execution receipts, then test them with a constructed supplier-selection case and a complete review-cost calculation.
At the CrownCAD 2027 launch, IDENIFE presented HuanYu's integration with CrownStyling, connecting design requirement understanding, visual concept generation and 3D concepts with a professional styling environment.
Opening a 3D file with a plausible appearance does not establish correct dimensions, orientation or component placement. For static mesh delivery, this article separates unit interpretation, coordinate-basis conversion and object transforms. A constructed millimeter-to-meter, Z-up-to-Y-up example supports hierarchy, normal and destination checks, with explicit limits for engineering use.
Readable speech recognition does not establish faithful meeting notes or confirm who committed to what. This article separates audio, speaker labels, summaries and actions, then proposes critical-fact checks, evidence playback and version confirmation. Constructed examples show how review effort changes the investment case for meeting assistants.
When people and agents modify the same object, valid parameters, successful requests and even idempotency do not prevent stale content from overwriting newer changes. A constructed order example explains conditional updates with ETag and If-Match, atomic server-side checks, conflict recovery and concurrency tests, while separating object versions from cross-object constraints and unknown write outcomes.
Shadow testing exposes a candidate AI system to live inputs without making its answers authoritative. It does not automatically establish business benefit or eliminate side effects. This article proposes an evidence checklist covering test boundaries, paired inputs, missing results and capacity, so teams can decide what supports a limited rollout and what still needs validation.
Applying one temperature formula to every field can corrupt temperature rises, rates and tolerance bands. Constructed Celsius, Fahrenheit and kelvin records explain offsets and scaling, followed by a versioned conversion workflow and counterexample tests. Correct units still do not establish that measurement points are comparable.
Higher source-image resolution does not establish that a model receives more useful detail, while crops can lose units, headers and object relationships. A constructed equipment-nameplate example compares whole images, local review and recapture, followed by an acceptance framework covering omissions, misreads, review effort and delivery cost.
Expanding a department and its descendants can fail through orphan nodes, cycles, overlapping roots and multiple parents. Constructed organization and order data separate node, path and fact grains, then support traversal checks, reconciliation and versioned publication. The article also explains why organizational deduplication must not be applied blindly to bill-of-materials quantities.
A hundred tests without an observed failure do not establish an enterprise AI error rate below one percent. This article separates calls, independent business samples and deployment exposure, explains how selection and repeated tuning weaken evidence, and connects acceptance design with review budgets and staged automation.
A total and its details can each be queried successfully yet disagree because they read different committed states. Scoped to PostgreSQL 18, this article uses a stock-transfer example to explain statement versus transaction snapshots, coordinated parallel reads and publication of a complete result set. It separates snapshot consistency, freshness and business completeness.
Separating permissions does not isolate performance when customers or departments share an AI service. Long-document processing, batches and tool calls can monopolize pooled resources. This article distinguishes rate limits, in-flight concurrency and minimum service commitments, then uses constructed capacity examples and mixed-tenant tests to guide isolation decisions.
A request-weighted average of instance P95 values is still not the service-wide P95. Hand-checkable examples explain raw samples, quantile summaries, histogram merging and bucket error. A classic Prometheus query and acceptance checks address missing timeouts, retry denominators and whether a latency dashboard represents the experience it claims to measure.
A closed page or expired request does not necessarily stop model inference or tool execution. Enterprise AI needs a contract for remaining time, cooperative cancellation, durable background work and evidence of resource release. Constructed examples and staged acceptance checks distinguish the end of waiting from stopped computation and reversed business effects.
A running total can jump across tied dates, a two-row window can span more than two days, and a display filter can discard opening history. A three-row example explains frame semantics and provides counterexamples and acceptance checks for enterprise analytics.
Continuous metric checks can repeatedly notify the same incident and mistake missing data for recovery. Separate observations, incidents and notifications, then validate state transitions, grouping, response deadlines and handling capacity with a constructed example.
Successful parsing and schema validation can conceal overwritten fields and rounded identifiers. This article develops representation contracts, early duplicate detection, explicit numeric conversion, cross-runtime tests and recoverable quarantine before data reaches business tables.
A draft model can accelerate generation while adding compute and memory costs. This article separates distribution guarantees from service performance and develops a workload-based decision framework using committed tokens, complete round time, peak capacity and constructed cost examples.
Correct daily customer counts do not add up to a monthly distinct count, and channel totals can exceed the overall population. Constructed data explain non-additivity, exact object-level counting and mergeable HLL sketches, followed by dimension design, deletion rebuilds, error evaluation and an exact-query fallback.
Reusing an answer can avoid an LLM call, but can also carry outdated policies, another customer's information or incompatible business conditions into a new request. This article defines reuse boundaries, separates useful hits from lookup hits, and develops constructed quality and cost examples plus a staged acceptance process.
Similar-looking names can contain different characters, while width, case or punctuation transformations can collapse distinct codes into one value. This article separates raw text, display values, search keys and identity keys. Constructed part numbers illustrate normalization and confusable-character limits, followed by collision handling, database comparison, version migration and counterexample tests.
A model generated from a sentence is not automatically editable or ready to manufacture. This article distinguishes visual assets, parametric models and engineering handoff, then develops an investment framework around part families, design intent, successive edits and complete labor costs. A constructed mounting-plate example shows what to test and when templates or manual modeling remain preferable.
Successful SQL can exclude orders with unknown status, return no results because an exclusion list contains NULL, or silently replace missing amounts with zero. Four constructed orders explain filtering, anti-matching, aggregation and outer joins, with explicit expected results and a practical null-policy acceptance workflow.
External material can redirect an assistant even when its tools stay within account permissions. This article traces trust across sources, transformations, decisions and outputs, then uses a constructed procurement scenario to evaluate layered controls, actual harm, legitimate-task utility and operating costs.
After an employee leaves a project, a RAG system can still return information through an old cache, a request that already passed authorization, or an answer being generated. This article separates revocation commits, authorization snapshots, and output release. Drawing on official Zanzibar, SpiceDB, and OpenFGA sources, it develops an event timeline, achievable revocation guarantees, and deterministic race tests that explain why another permission check is not the same as recalling data.
Digital twins can generate labeled industrial images at scale, but visual realism alone does not establish production readiness. This article develops an investment and validation framework around defect visibility, camera imaging, constrained randomization, and tests under real operating conditions. An explicitly constructed conveyor example shows when to add data, calibrate the simulation, or improve the imaging hardware first.
A successful CSV read does not establish fidelity. Leading zeros can disappear, valid NA codes can become missing values, and embedded newlines can be mistaken for records. This article provides an input contract, constructed example, quarantine policy and replay acceptance workflow before data reaches production tables.
Faster work after an AI rollout does not establish that AI caused the improvement. Task selection, staffing, simultaneous process changes and missing failures can distort the result. This article connects experimental design with complete workflow accounting to support decisions to expand, investigate further or defer investment.
Successful page responses do not establish a complete dataset. Inserts, deletes and changing sort fields can cause duplicates or omissions, and a cursor does not inherently provide a snapshot. Constructed order lists explain offset and keyset pagination, followed by a workflow for stable views, checkpoint commits, expired-token recovery and key-set reconciliation.
Abstention can reduce incorrect automated decisions while moving work into a queue. Enterprises need to evaluate coverage, errors among accepted results and what happens to deferred requests together. This article separates confidence scores from probabilities, proposes independent threshold acceptance and uses a constructed example to show why higher accuracy need not produce a better service.
Averaging departmental rates, silently skipping missing values or overlooking a change in channel mix can produce misleading analytics. Constructed examples distinguish overall conversion, an equal-weight department average and a fixed-mix comparison, then turn those distinctions into calculation contracts, missing-data states and regression checks.
Changing a model name does not establish provider portability. Prompts, file identifiers, conversation state, tool outcomes and diagnostic evidence can all create dependencies. This article proposes an asset inventory, state handover, an exit rehearsal and a migration cost ledger to help teams decide what to standardize, what to retain as provider-specific, and when a dual-provider setup is not worth building.
Two decimal places on screen do not establish consistent calculation rules. Constructed examples explain decimal representation, line versus total rounding, allocation residuals, nulls and transport boundaries, followed by a reproducible monetary contract and reconciliation process.
Prompts, retrieved passages and tool responses can create sensitive copies throughout an AI troubleshooting pipeline. This article develops purpose-based collection, separated evidence access and time-limited debugging, with a constructed example that tests both missed redaction and lost diagnostic value.
Storing UTC does not guarantee correct daily totals. This guide separates instants, local clock times and business dates, with half-open query windows, daylight-saving examples and acceptance tests for AI-assisted analytics.
Backups of models, indexes and databases do not prove that an AI service can recover. This article defines recovery objectives, a coherent recovery inventory and acceptance tests, then uses a hypothetical timeline to compare restore-based recovery with standby capacity.
Replacing an embedding model is more than changing an endpoint. Matching dimensions do not establish compatible vector spaces, while thresholds, caches and incremental writes can conceal mixed versions. This article develops a rebuild, reconciliation, evaluation and rollback process, with constructed examples for capacity and failure handling.
Selecting a model's most uncertain examples does not necessarily reduce annotation costs. Difficult cases can take longer to label, while repeated ambiguities crowd out missing business coverage. This article separates training acquisition from measurement, then proposes a cost-based comparison, exploration samples and explicit exit conditions for enterprise investment.
A source column addition, type change or revised monetary definition can distort reports and AI analytics while pipelines still report success. This article separates read/write compatibility, business meaning and operational cutover. A constructed order migration explains version isolation, historical replay, consumer upgrades and recovery, with counterexample tests that go beyond passing schema validation.
An AI endpoint can return successfully while delivering the wrong business answer, and more logs do not necessarily make failures easier to diagnose. This article separates runtime status, business outcomes and diagnostic evidence, then develops minimum trace records, sampling choices and fault exercises. A constructed storage example exposes both cost and diagnostic blind spots.
Should last year's revenue move when a customer changes sales regions? The answer depends on whether the question concerns transaction-time ownership, today's organization or information known when a report was released. This article explains effective-dated joins, snapshot limitations and practical tests for corrections, missing history, overlapping versions and group-level reconciliation.
Adding an approval button does not create reliable human–AI collaboration. Reviewers need verifiable evidence, enough time and genuine authority to reject. This article develops an acceptance framework for review workload, routing, evidence presentation and timeouts, with a constructed calculation showing how expanded automation can turn the review queue into the delivery bottleneck.
A sensor table with one row per minute is not automatically ready for modeling. Bucket boundaries, sampling density, imputation spans and future observations can change what the signal means. Using constructed temperature sequences, this article separates aggregation from interpolation and develops an implementation and acceptance process that preserves evidence, limits filling, and distinguishes real-time inputs from revised offline views.
More accurate fault predictions do not automatically reduce downtime. Value depends on whether alerts arrive early enough for maintenance, whether parts and staff are available, and what false alarms, missed failures and early replacement cost. Drawing on primary research, this article develops an investment framework from failure modes to controlled acceptance, with a constructed example showing why the same model can produce opposite decisions at different plants.
Repeated prompts do not prove cache hits, and cache hits do not prove business gains. This article develops an acceptance method covering prefix structure, usage accounting, cold and warm benchmarks, cost modelling, tenant boundaries and rollback.
Whether multi-model routing reduces the total cost of enterprise AI depends on which requests can safely use a lower-cost model and which errors are escalated in time. This analysis separates pre-generation routing from post-generation cascades, uses reproducible hypothetical calculations, and sets out procurement and exit criteria covering cost, tail latency and false approvals.
A smaller four-bit model file does not guarantee proportional runtime-memory savings, faster inference or unchanged quality. This article distinguishes weights, activations and KV cache, then develops a reproducible memory example, calibration-data requirements and controlled comparisons. Paired business cases reveal regressions that average scores can conceal.
Transferring behavior from a large model to a smaller one is not a low-cost copy of every capability. Drawing on distillation documentation and recent research, this article separates teacher supervision, student fit and business acceptance. A decision framework and constructed cost example show how task stability, review and fallback rates determine whether the investment is worthwhile.
A generated SQL query can execute successfully while joins between detail tables inflate its totals. Using a constructed order, item and payment example, this article explains fanout, why deduplicating monetary values fails, when to use pre-aggregation, existence filters or allocation rules, and how cardinality checks and counterexample tests can verify the result.
An input distribution change does not establish model failure, and retraining does not resolve every performance decline. This article separates data faults, population shifts and changing prediction relationships, then presents a decision process for repairing data, collecting evidence, limiting automation and evaluating retraining—with explicit treatment of delayed labels, baselines and maintenance costs.
A knowledge base may answer conceptual questions yet miss an exact model number or confuse neighboring part numbers. The fault can lie in field design, candidate truncation, or reranking. Using a constructed equipment-manual scenario, this article explains lexical and vector retrieval, the limits of RRF, and a practical evaluation method that traces evidence through the pipeline and compares results by query type.
Generating large training datasets is easier than proving their value in real operations. Synthetic data can address coverage gaps that are describable and verifiable, but it cannot replace knowledge of the real distribution. Drawing on model-collapse research and generation-tool documentation, this article offers an investment framework covering gap definition, retention of real data, training exposure, and independent acceptance, with a constructed scenario for comparing benefits, costs, and stopping conditions.
Customer deduplication across systems requires more than name similarity. This article develops a verifiable, reversible mapping process covering entity definitions, candidate recall, evidence, human review and cluster conflicts. It explains why a high match rate can hide false merges and how independent samples reveal missed and incorrect links. Examples are constructed; thresholds require calibration to business losses.
LLM judges can expand evaluation coverage, but may mistake fluency, length or answer position for quality. This article separates preference comparison, factual checking and release decisions, then uses an independent human reference set and a constructed example to show why high agreement can still conceal critical false approvals.
Correctly recognized text can still become incorrect data through shifted columns, lost merged headers or faulty page stitching. This article separates regions, grids, header paths and evidence mapping, then uses a constructed inspection table to define structure preservation, continuation handling and business-field acceptance.
Batch inference offers an alternative to immediate responses, but a lower API bill does not establish lower business cost, and server-side completion does not establish on-time delivery. This article budgets preparation, queueing, validation, recovery and release, with constructed examples for deciding when asynchronous processing is appropriate.
Inventory queries often fail through semantics rather than SQL syntax: treating balances as flows, missing dates as zero, or the latest records as a complete period-end position. This article defines a daily-snapshot contract, explains closing and average inventory with constructed examples, and provides implementation steps and acceptance cases for data teams.
Longer model inputs give enterprise knowledge systems another option: reading a defined document collection directly. Capacity alone does not ensure complete evidence or lower cost. This article compares retrieval, long-context and hybrid approaches through evidence scope, workload and end-to-end cost, then sets out a practical comparative evaluation.
How can a company turn a business problem into a custom AI project? A constructed after-sales ticket-routing scenario illustrates scope, sample validation, human handover, system integration and acceptance criteria before procurement.
What should an enterprise ask in its first conversational analytics demo? Start with three business questions, existing reports, metric definitions and access boundaries. Separate sample-data exploration from validation on company data before deciding whether IDONE fits.
A successful vector write does not complete a RAG knowledge-base update. Chunks, lexical and vector indexes, and answer caches may represent different revisions, while deleting a source file may leave retrieval copies intact. This article separates acknowledgment, visibility and activation, then develops a revision manifest, a prepare–validate–activate protocol and a deletion high-water mark, with failure scenarios and measurable acceptance criteria.
A working connection and a valid login do not establish that an enterprise agent may perform a particular business action. This article proposes a delegation framework covering objects, operational limits, validity and data destinations. A constructed maintenance workflow shows how approval, execution and audit should connect, giving enterprise teams practical criteria for rollout and supplier acceptance.
IDENIFE examines the data pipeline behind embodied AI: choosing egocentric capture hardware, aligning video, IMU and robot actions, building useful annotations, and connecting LeRobotDataset v3.0 to NVIDIA GR00T. An illustrative industrial sorting workflow grounds the discussion of embodiment transfer, synthetic data, acceptance criteria and scaling costs.
A chronological train–test split can still use backfilled production figures, immature labels or future variables unavailable in service. A constructed daily seven-day electricity forecast explains rolling origins, availability timestamps, training gaps and horizon-specific errors, with a replay procedure that follows real prediction and retraining schedules.
Local inference reduces dependence on external connectivity but brings updates, storage and incident handling to the site. Drawing on a recent industrial vision study and edge-platform documentation, this article allocates work by deadlines, offline dependencies, data transfer and maintenance responsibilities, then calculates outage backlog and recovery in a constructed scenario.
Valid JSON can still turn unknown values into zeros, confuse monetary units or copy a field from the wrong document. Using a constructed quotation-extraction task, this article distinguishes response completion, structural constraints, business consistency and source evidence. It develops exception routing, controlled repair and acceptance metrics for traceable, reviewable candidate records.
A stronger general benchmark does not establish that a new model can safely replace an existing enterprise application. Parameters, reasoning defaults, response parsing and tool selection may change. Drawing on migration documentation, agent evaluations and canary releases, this article proposes four kinds of upgrade evidence and shows how aggregate gains can conceal critical regressions.
A high AUROC does not establish that an industrial vision model will miss few defects or produce a manageable number of false alarms on a production line. This article develops an acceptance method around fixed thresholds, part-level statistics, lighting and batch changes, evidence for rare defects, and human review capacity. Explicitly constructed data illustrate the operational workload.
Fitting a model into GPU memory does not establish that employees can use it reliably during peak demand. Drawing on the recent expansion of inference benchmarks to end-to-end workflows, this article proposes assessing private deployment through task quality, response deadlines, workload patterns and failure conditions. A constructed example shows how load-test evidence can guide procurement, scheduling and expansion.
A dataset can load successfully and contain every required field yet still be unsuitable for training. Using a constructed support-ticket classification example, this article explains how to define acceptance boundaries and check exact and near duplicates, temporal and entity leakage, label quality, and version traceability. Acceptance should establish fitness for the agreed task, rather than impose one universal pass rate on every dataset.
A successful demonstration does not necessarily justify greater investment. This article proposes assessing enterprise AI across the full workflow, considering data readiness, human review, error recovery, business accountability and ongoing costs. Define the deliverables and risk limits first, measure net benefits next, and expand gradually within clear business boundaries.
An order, payment, and refund example explains snapshot boundaries, out-of-order updates, deletion, idempotency, and data contracts—and how to validate the result through replay and reconciliation.
Distinguish single-image inference from multi-image reconstruction, compare meshes, NeRF and 3D Gaussian Splatting, and define delivery checks for topology, scale, UVs, materials and runtime behavior.
What do diffusion, DiT and Flow Matching actually contribute? Build a traceable concept workflow across text and spatial conditions, local CMF edits, geometric consistency and manufacturing review.
When multiple agents enter business workflows, duplicate calls, conflicting state, and unknown outcomes become central problems. A hypothetical replacement-parts process illustrates how to make tool execution constrained, recoverable, and verifiable.
Connecting enterprise knowledge to a model leaves critical work between retrieval and the final answer. This article examines permissions, versions, hybrid search, reranking, claim-level citations, and abstention as parts of a testable evidence trail.
Follow a question about last month’s East China net sales through metric semantics, schema retrieval, time definitions, read-only permissions, cost controls, and result evaluation.
Understand text, images and data, evaluate generated results, then select models for the task.
From a model foundation to orchestration and tool invocation: the role of an execution framework.
AI capabilities, working facilities, training and industry connections in IDENIFE’s OPC space.